We have n jobs, where every job is scheduled to be done from startTime[i] to endTime[i], obtaining a profit of profit[i].
You're given the startTime, endTime and profit arrays, return the maximum profit you can take such that there are no two jobs in the subset with overlapping time range.
If you choose a job that ends at time X you will be able to start another job that starts at time X.
Example 1:
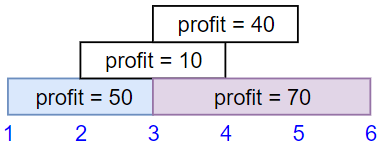
Input: startTime = [1,2,3,3], endTime = [3,4,5,6], profit = [50,10,40,70]
Output: 120
Explanation: The subset chosen is the first and fourth job.
Time range [1-3]+[3-6] , we get profit of 120 = 50 + 70.
Example 2:
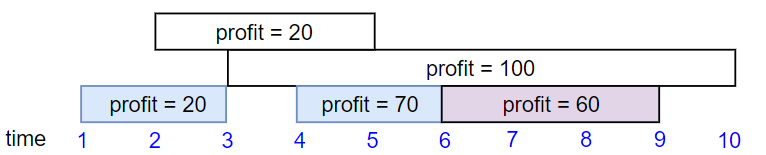
Input: startTime = [1,2,3,4,6], endTime = [3,5,10,6,9], profit = [20,20,100,70,60]
Output: 150
Explanation: The subset chosen is the first, fourth and fifth job.
Profit obtained 150 = 20 + 70 + 60.
Jobs must not overlap. \(n \le 5\times 10^4\) rules out subset search. Whether we take job \(i\) only affects jobs that start no earlier than its end.
After sorting by start, \(\textit{dfs}(i)\) takes the better of skipping \(i\) and taking \(i\) then jumping to the first job with \(\textit{start}\ge \textit{end}_i\). That index is a binary search on the sorted starts. Memoization evaluates each \(i\) once.
First, we sort the jobs by start time in ascending order, then design a function \(\textit{dfs}(i)\) to represent the maximum profit that can be obtained starting from the \(i\)-th job. The answer is \(\textit{dfs}(0)\).
The calculation process of function \(\textit{dfs}(i)\) is as follows:
For the \(i\)-th job, we can choose to do it or not. If we don't do it, the maximum profit is \(\textit{dfs}(i + 1)\); if we do it, we can use binary search to find the first job that starts after the end time of the \(i\)-th job, denoted as \(j\), then the maximum profit is \(\textit{profit}[i] + \textit{dfs}(j)\). We take the larger of the two. That is:
Solution 1 sorts by start and fills one suffix table. Sorting by end instead, \(dp[i]\) is the best profit among the first \(i\) jobs: skip inherits \(dp[i-1]\); take adds \(dp[j]\) for the last job that ends before this start, with \(j\) still from binary search.
Solution 1 sorts by start and fills a suffix table. Here we sort by end and define a prefix table.
First, sort the jobs, this time we sort by end time in ascending order, then define \(dp[i]\), which represents the maximum profit that can be obtained from the first \(i\) jobs. The answer is \(dp[n]\). Initialize \(dp[0]=0\).
For the \(i\)-th job, we can choose to do it or not. If we don't do it, the maximum profit is \(dp[i]\); if we do it, we can use binary search to find the last job that ends before the start time of the \(i\)-th job, denoted as \(j\), then the maximum profit is \(\textit{profit}[i] + dp[j]\). We take the larger of the two. That is:
Jobs must not overlap. \(n \le 5\times 10^4\) rules out subset search. Whether we take job \(i\) only affects jobs that start no earlier than its end.
After sorting by start, skipping calls \(i+1\) before it returns, so the chain has length \(n\) and overflows the stack.
Later indices are known if we walk from the end. Let \(f[i]\) be the best profit from job \(i\), with \(f[n]=0\), and binary-search the next compatible job while filling \(i\) from \(n-1\) down to \(0\).
First, we sort the jobs by start time in ascending order. Let \(f[i]\) be the maximum profit that can be obtained starting from the \(i\)-th job. The answer is \(f[0]\), and \(f[n] = 0\).
Fill \(i\) from \(n - 1\) down to \(0\). For the \(i\)-th job we can skip it, which keeps \(f[i + 1]\), or take it. Binary search finds the first job \(j\) that starts at or after \(\textit{end}_i\). Taking it earns \(\textit{profit}[i] + f[j]\). Take the larger of the two:
\[ f[i]=\max(f[i+1],\textit{profit}[i]+f[j]) \]
Where \(j\) is the smallest index that satisfies \(\textit{startTime}[j] \ge \textit{endTime}[i]\). Because \(j > i\), \(f[j]\) is already filled.
The time complexity is \(O(n \log n)\), where \(n\) is the number of jobs.